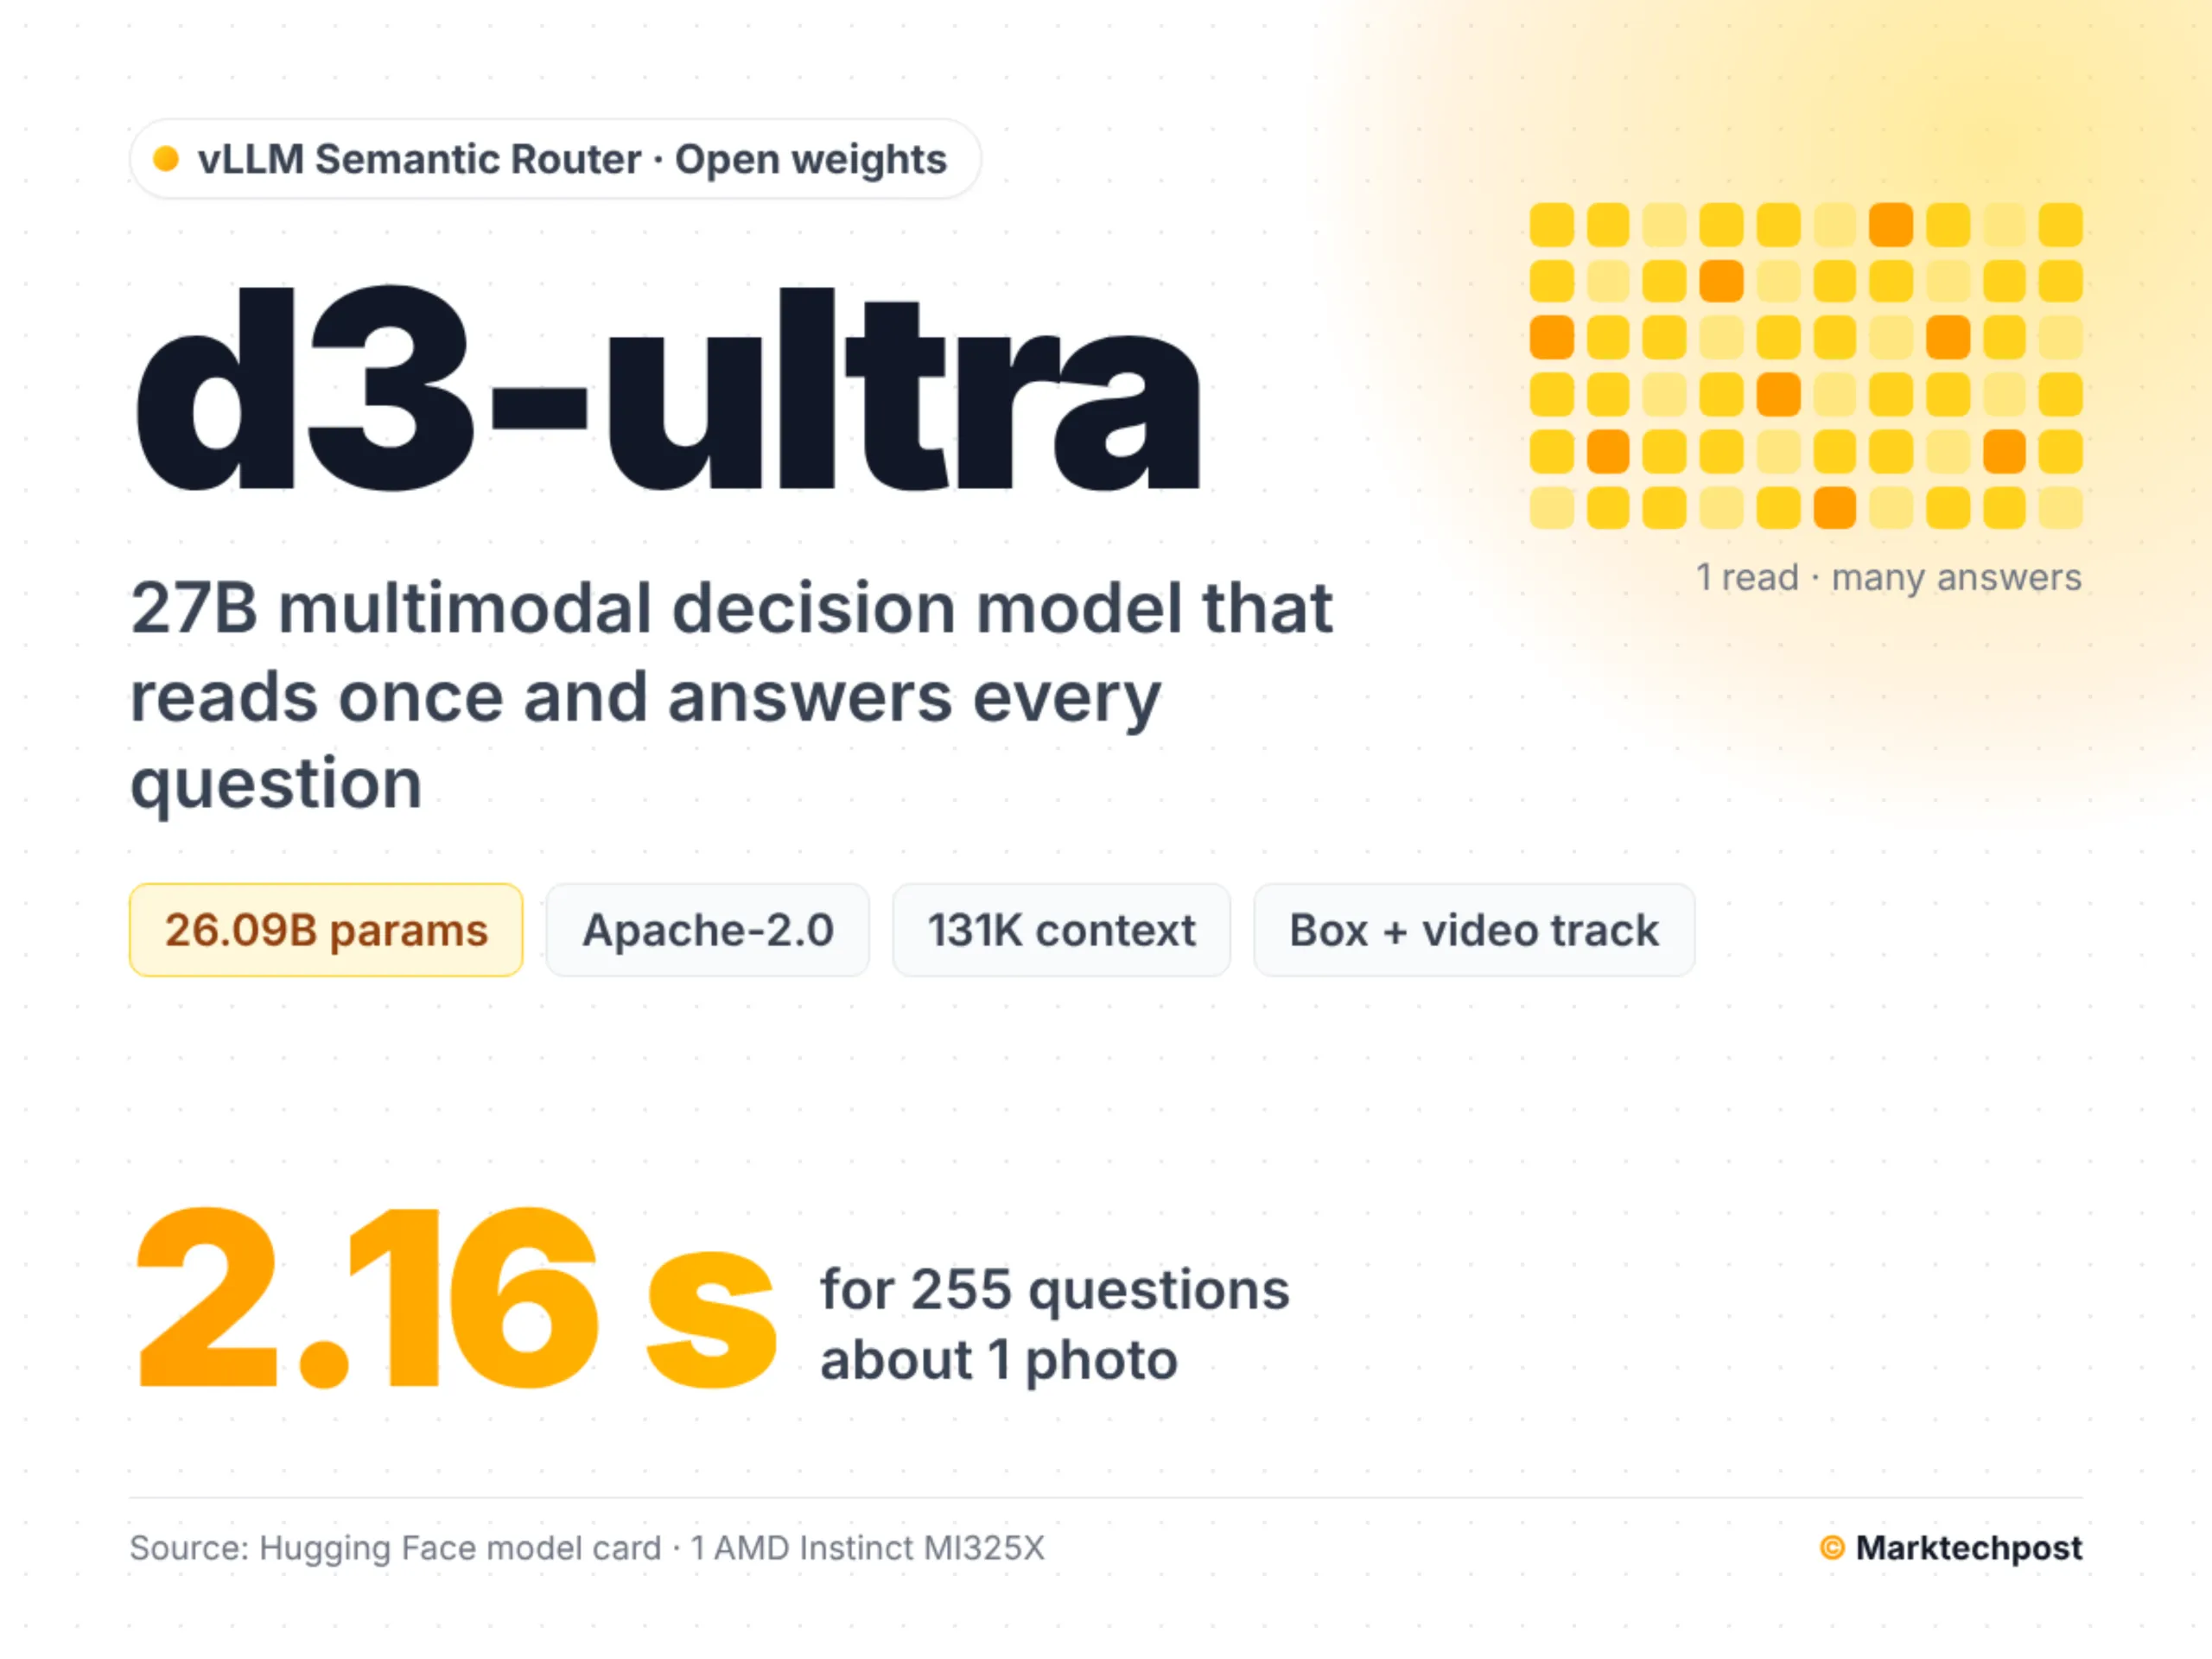
The vLLM Semantic Router team has released d3-ultra, a 27B multimodal decision model under Apache-2.0. The d3-ultra decision model does not generate text. It reads an input once and returns a probability for every answer to every question. For developers, that means routing, classification, visual grounding and video checks from 1 open-weight call.
TL;DR
- Size: 26.09B parameters (dense, including a 0.46B vision encoder); 131,072 tokens of context per question.
- Runs on: tested on 1 AMD Instinct MI325X with BF16 weights; no official quantized variant is listed yet.
- Performance: highest SR-Text score of the 6 decision models in the team’s own private test.
- Best: 97.8 on SR-Text tools and automation (chance-corrected accuracy).
- Worst: 54.6% on SR-Box (9 domains), 5.0 points below its sibling d3-turbo.
What is d3-ultra?
d3-ultra is a System One decision model from vLLM Semantic Router that answers typed questions with probabilities. It is the newest member of Decision 3.0, a family that spans 0.6B to 27B.
You send a state (text or JSON, plus images or videos) and a set of questions. Each question has a type:
- Choice: pick 1 of several options.
- Yes / No: return the probability of yes.
- Score: rate on a scale.
- Box: locate something in an image or a video moment.
- Track: follow a target across a whole video.
Images can also sit inside questions and options. A quiz can show a photo, then offer 4 etchings as answers.
How does d3-ultra work?
The core idea is state once. The model reads the input once per request and answers every question from that single read.
The config shows a Qwen3.5-architecture backbone with 64 layers. 48 are linear-attention layers and 16 are full-attention layers. The card does not name its base checkpoint. vLLM’s recipe says the sibling d3 was trained from Qwen3.8-27B.
Box answers always return exactly 1 box with a confidence. A confidence near 0 means the target is not in the picture. Questions over 131,072 tokens fail with max_length_exceeded; nothing is silently truncated.
How does d3-ultra perform on benchmarks?
The research team compares d3-ultra with GLiDE V1.2, d1-ultra, d3-turbo, d3 and Jev 1.14 on 2 in-house tests.
SR-Text has 10,411 text requests with 73,495 questions. Most recreate skills from 34 public benchmarks with new items. Another 4,896 questions come from 43 new task families, like SQL checks and ticket routing. Scores are chance-corrected: 0 is chance, 100 is perfect.
- d3-ultra: 87.2
- GLiDE V1.2: 85.1
- d1-ultra: 83.4
- d3-turbo: 83.1
- d3: 81.4
- Jev 1.14: 73.1
d3-ultra leads every area except arts and human taste. There, d1-ultra scores 90.8 against 89.6, within the margin of error.
SR-Box has 5,678 Box questions on 4,984 images across 10 domains. A box counts as correct at IoU 0.5 or higher. d3-ultra scores 58.2% over 10 domains and 54.6% over 9. d3-turbo scores 60.0% and 59.6%. Jev 1.14 scores 45.7% and 46.9%. The team says d3-turbo stays stronger on natural images, while d3-ultra leads on charts.
Latency: on 1 AMD Instinct MI325X with AutoModel, 1 question about a photo takes 304 ms. 255 questions take 2.16 s, about 7.3 ms per extra question.
How do you deploy d3-ultra?
There are 4 routes:
- Transformers: AutoModel.from_pretrained(“vllm-sr/d3-ultra”, trust_remote_code=True) with transformers==5.17.0. The optional flash-linear-attention package adds fast GPU kernels.
- vLLM Semantic Router Engine: vllm-sr serve -e vllm-sr/d3-ultra, added in PR #5449 on October 25, 2026.
- Free API: the card says decision.vllm-sr.ai serves d3-ultra, with a free key.
- Demo: the official Hugging Face Space.
d3-ultra vs GLiDE V1.2, d1-ultra, Jev 1.14 and d3-turbo
Key Takeaways
- d3-ultra is a 27B Apache-2.0 decision model that never generates text.
- It reads input once: 255 questions about 1 photo take 2.16 s.
- It tops the team’s SR-Text test at 87.2, ahead of GLiDE V1.2 at 85.1.
- It trails d3-turbo on Box grounding: 58.2% vs 60.0%.
- All benchmark numbers are self-reported on private test sets.
Check out the model card, the GitHub repo, the Decision 3.0 collection and the Hugging Face Space. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.