NVIDIA is using Palantir Foundry and cuOpt to automate its hardware supply chain allocation decisions across global manufacturing sites.
The company measures operational delivery from wafer-out to first token. This window splits into time-to-rack (the transit from fab output to an assembled data centre system) and time-to-token (which covers power, cooling, networking, and day-one software readiness.)
Managing NVL72 and Vera Rubin component flows
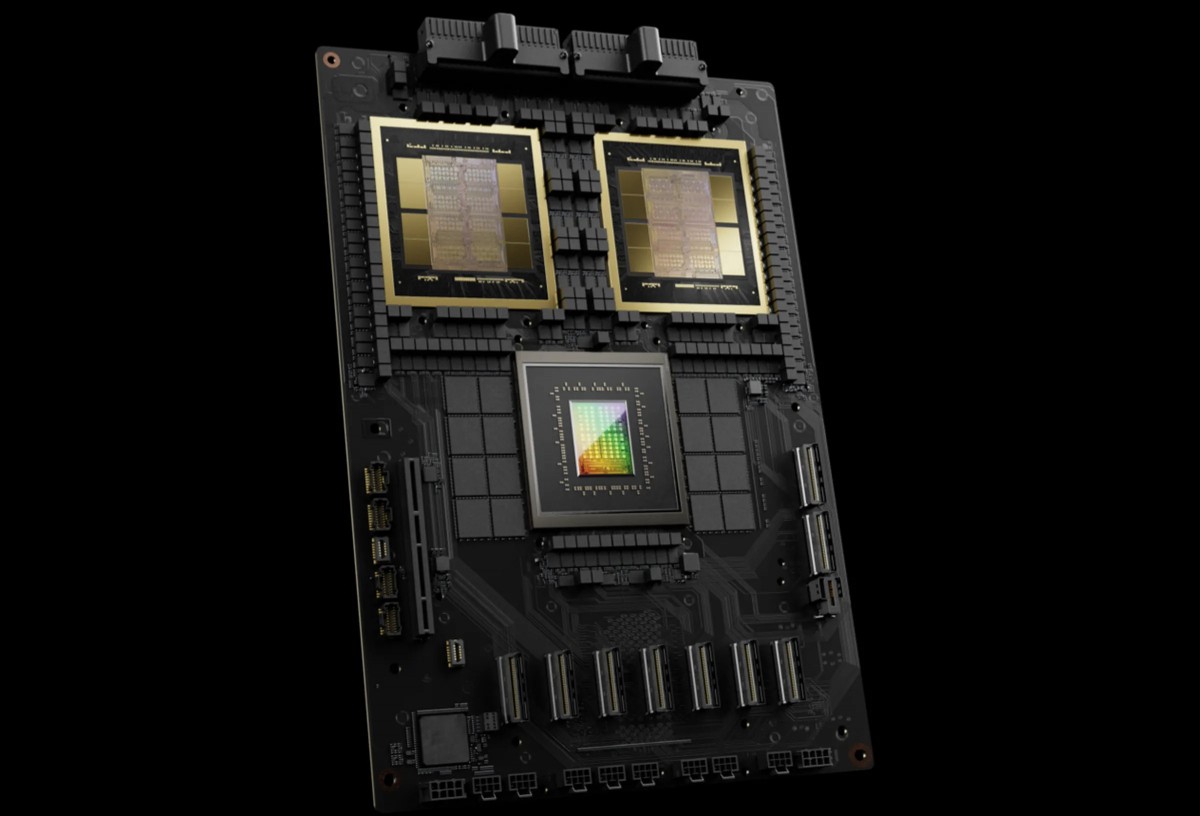
Hardware scaling has magnified supply constraints. An NVIDIA Grace Blackwell NVL72 rack contains 18 compute trays, with each tray requiring two Grace CPUs, four Blackwell GPUs, and 32 HBM3e memory packages sourced across thousands of suppliers, OEMs, and contract design partners.
The upcoming supply chain constructed for NVIDIA’s Vera Rubin architecture is twice as large as the network supporting Grace Blackwell.
Assembly cannot proceed until parts arrive from three designated channels: direct inventory, consignment stock, and external suppliers. Early shipments must wait on delayed components, extending the metric NVIDIA terms ‘Time of Ownership’ (the duration from when a facility receives materials to when finished sub-assemblies depart.)
Factory allocations are reworked weekly over rolling two-quarter horizons to resolve part availability, throughput limits, and customer fulfilment schedules.
Mixed-integer linear programming via cuOpt
To coordinate these dependencies, the NVIDIA operations team built the ‘Digital Supply Chain Intelligence’ command centre using Palantir Foundry. Foundry’s Ontology models facilities, supplier commits, component stocks, and production targets as interconnected objects and links.
NVIDIA cuOpt, an open-source library for GPU-accelerated decision optimisation, reads this operational layer directly. Formulating distribution as a mixed-integer linear program designed to minimise TOO, the solver evaluates parts constraints across every tier of the bill of materials.
Beyond outputting weekly delivery schedules, cuOpt identifies active factory limits, such as regional assembly capacity caps versus raw memory availability.
Training Nemotron on qualitative operational records
Mathematical optimisation alone failed to capture unstructured operational variables observed by human planners, including supplier call transcripts, regional weather forecasts, partner email exchanges, and geopolitical events.
NVIDIA addressed this by post-training Nemotron 3.5 Lightning, an open-weight mixture-of-experts model featuring 30 billion total parameters and approximately three billion active parameters per forward pass.
The engineering pipeline processes historical records through NeMo Anonymizer to redact sensitive operational fields, NeMo Data Designer to balance training examples with synthetic capacity disruption scenarios, and NeMo AutoModel to apply low-rank adaptation (LoRA) parameters while keeping base model weights frozen. Palantir Autopilot manages data lineage, model tracking, and recommendation delivery.
Production benchmarks and future reinforcement learning
Evaluated on historical allocation records, the post-trained Nemotron 3.5 Lightning model achieved 86.7 percent decision accuracy, compared to 55.5 percent for the larger Nemotron 3 Ultra model and 17.5 percent for the un-tuned Lightning base model.
The post-trained model achieved a 58.6 percent balanced accuracy and a 57.5 percent macro-F1 score, outperforming Nemotron 3 Ultra’s 42 percent balanced accuracy and 39.5 percent macro-F1 score.
Fine-tuning completed on two NVIDIA B200 GPUs within minutes. Domain fine-tuning improved allocation decisions, though production risk forecasting further into the future remained difficult.
Operational choices, planner revisions, overrides, and observed factory outputs are continuously written back to the Palantir Ontology.
NVIDIA confirmed this dataset will form preference pairs for reinforcement learning routines – scoring recommendations on allocation precision, policy compliance, and evidence grounding – with production models remaining strictly isolated from live and unmonitored retraining.
See also: Supply chains detect fast, act slow: How AI agents fix it

Want to learn more about AI and big data from industry leaders? Check out AI & Big Data Expo taking place in Amsterdam, California, and London. The comprehensive event is part of TechEx and is co-located with other leading technology events including the Cyber Security & Cloud Expo. Click here for more information.
AI News is powered by TechForge Media. Explore other upcoming enterprise technology events and webinars here.