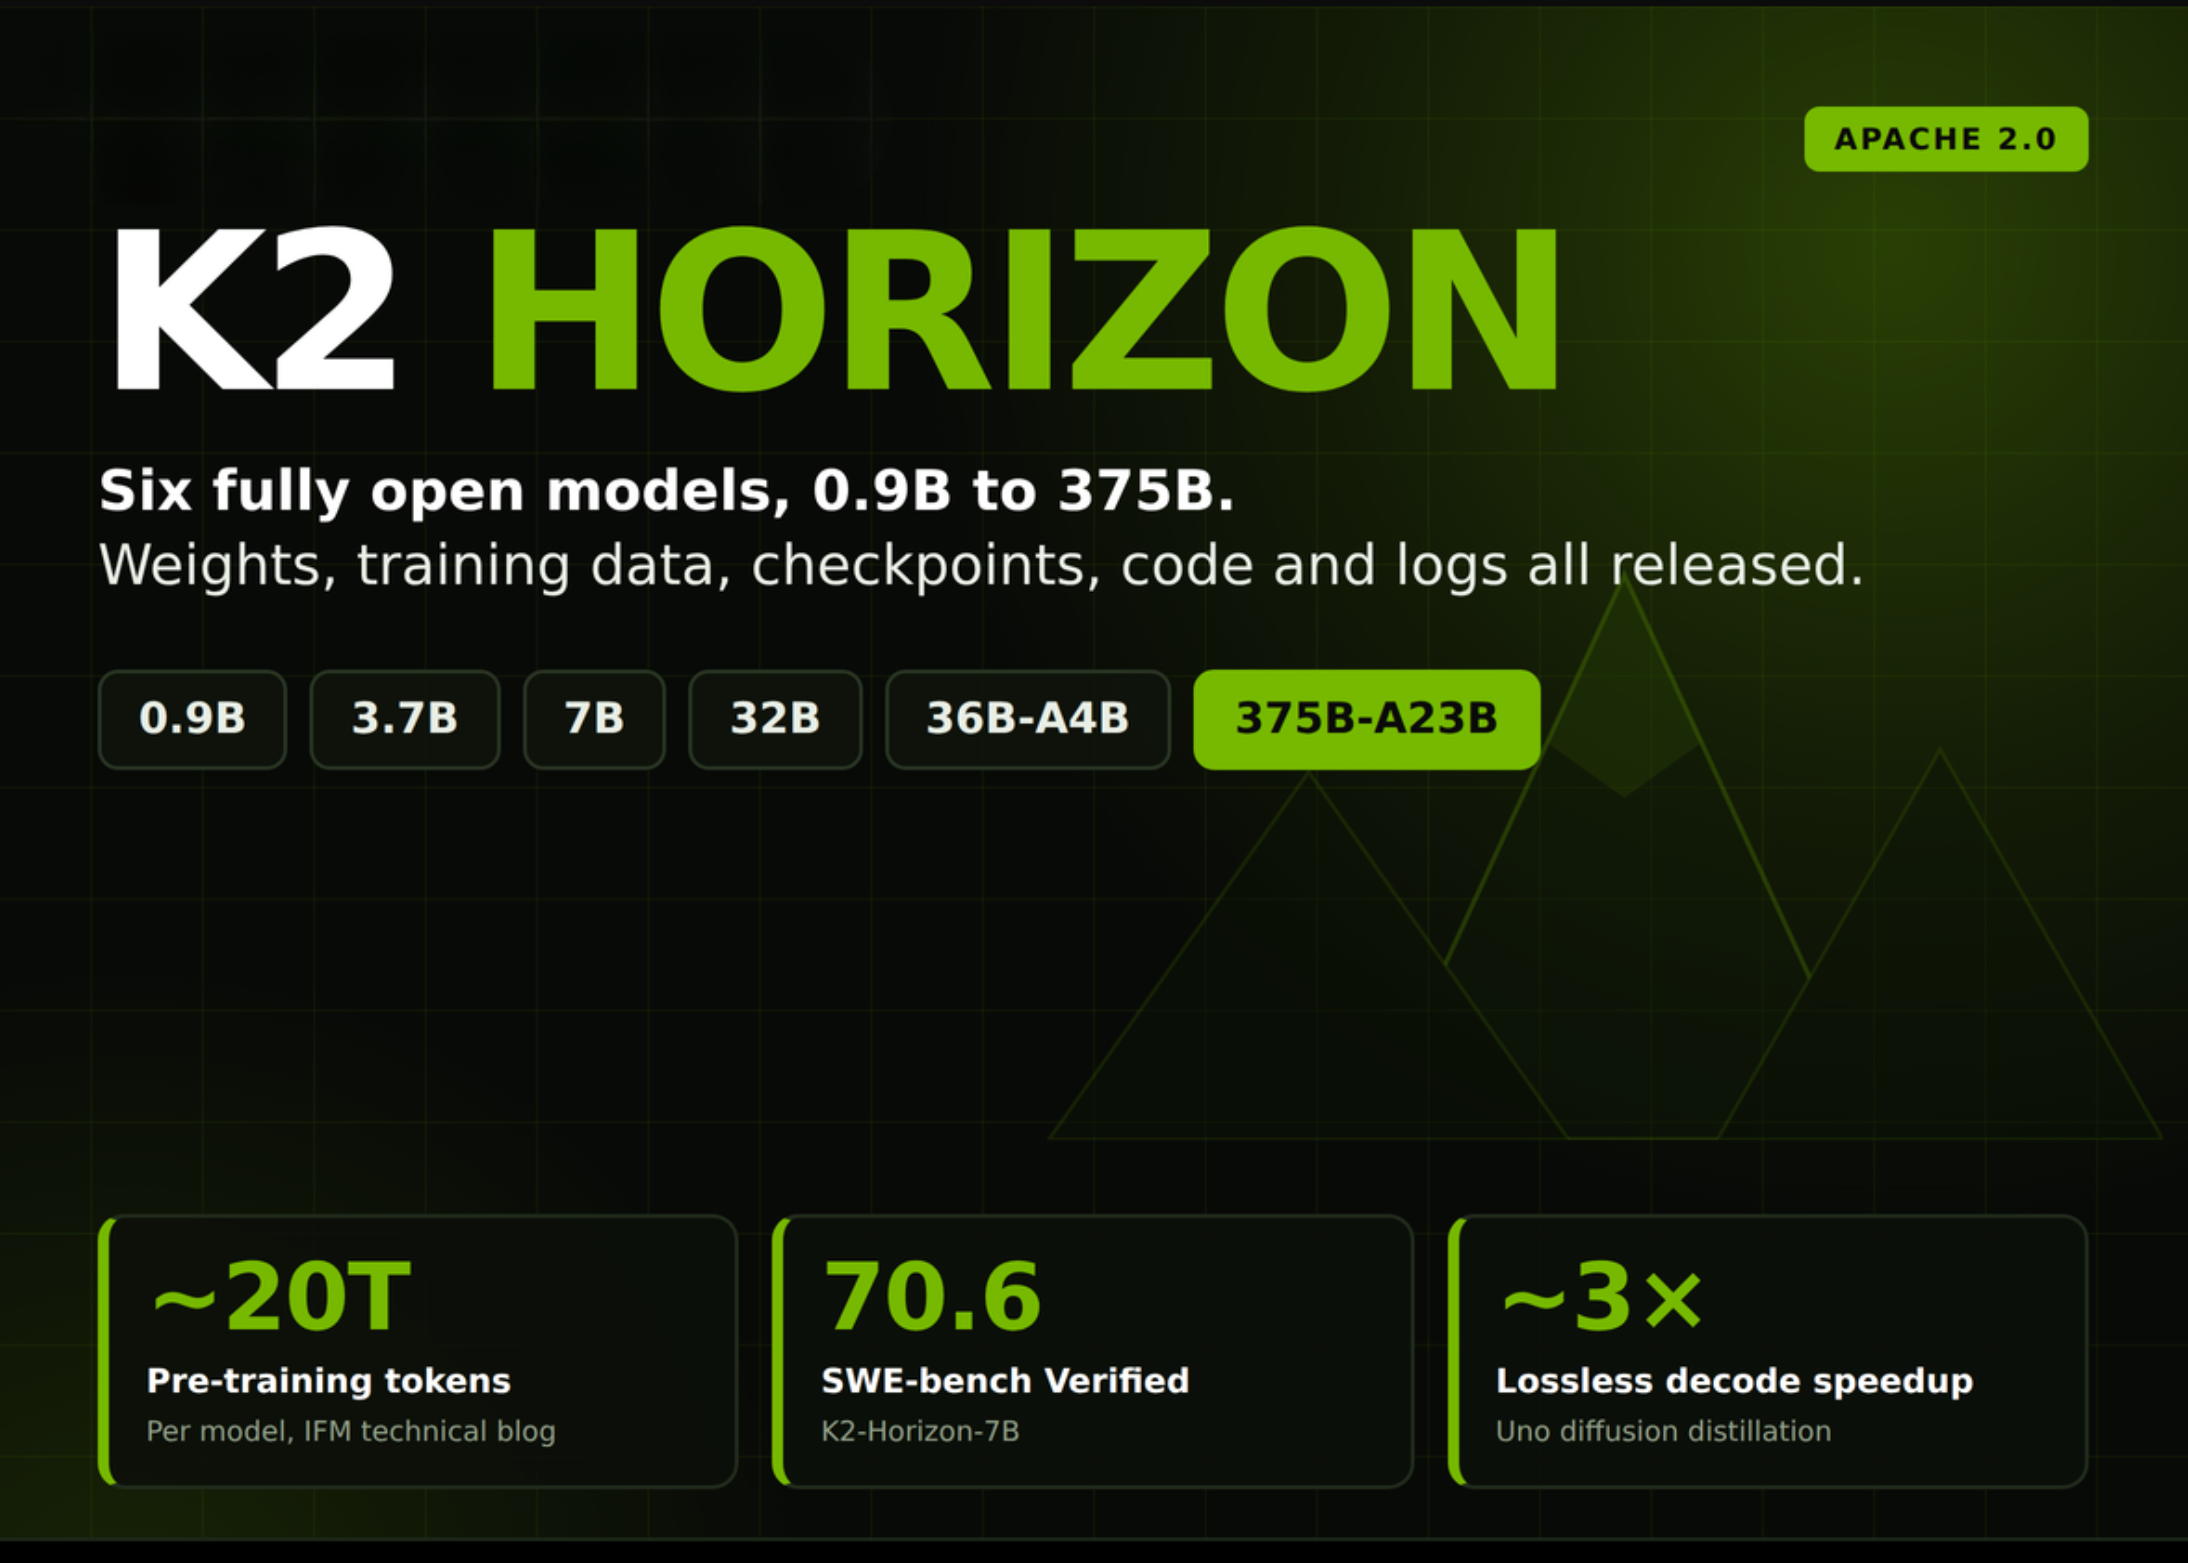
Most open model launches release one checkpoint and a benchmark table. The Institute of Foundation Models (IFM) released something wider last week. IFM is the frontier lab launched by MBZUAI in May 2025. K2 Horizon is a fleet of six models: 375B-A23B, 36B-A4B, 32B, 7B, 3.7B and 0.9B. Shipping alongside them are the pre-training corpus, intermediate checkpoints, training code, configs and fine-grained logs. IFM calls it the largest fully open-source model launch in AI history.
Is it deployable? Yes, all six sizes sit on Hugging Face under Apache 2.0, with FP8 and GGUF builds. Day-zero support covers vLLM, SGLang and Ollama, on NVIDIA, AMD and Cerebras hardware. Hosted APIs run through Compass, Cerebras and Nebius via platform.ifm.ai.
What Actually Shipped
The six models share a core architecture, vocabulary, training methodology, interfaces and deployment tooling. The 0.9B model uses a smaller vocabulary. That consistency is the point: teams can prototype on 3.7B and scale to 375B-A23B without changing their serving stack.
Each model is pre-trained on roughly 20 trillion tokens. Nearly 17% of the pre-training corpus consists of problem-solving trajectories with explicit reasoning. About 10 trillion tokens were synthetic.
Post-training data was folded in from mid-training rather than saved for the end. IFM research team reports over 100 million unique synthesized tasks. Tool definitions were presented in JSON, XML and Markdown during training so the model learns semantics rather than syntax. Markdown became the inference default, roughly 18.5% more token-efficient than JSON on IFM’s data.
MoVA: Sparsity Moved into Attention
Conventional Mixture-of-Experts applies sparsity to feed-forward layers. Mixture-of-Value Attention (MoVA) extends expert routing into multi-head attention itself, opening a second axis for scaling capacity. It stays compatible with FlashAttention, grouped-query attention and sparse attention.
The result is K2-Horizon-MoVA-36B-A4B: 36B total parameters, roughly 4B active per token. Under matched training conditions it lands slightly below the dense 32B model. On IFM’s tables it posts 58.6 on Terminal-Bench 2.1 and 26.8 on tau3-Banking, leading its comparison set on both.
Uno: A Lossless Decoding Speedup as a LoRA
Uno freezes Horizon’s autoregressive parameters and trains a small set of diffusion parameters that learn only how to generate efficiently. Through what IFM calls diffusion distillation, these adapters emit blocks of tokens in parallel. The press release puts the speedup at roughly 3× with no quality degradation. It ships as a LoRA adapter, currently 7B-Uno and 0.9B-Uno.
Numbers worth knowing
K2-Horizon-375B-A23B scores 70.2 on Terminal-Bench 2.1, 1,441 Elo on GDPVal-AA, 67.7 on MCPMark and 87.3 on GPQA Diamond. It leads its table on SWE-Atlas-QnA at 48.4 but trails GPT-5.6 Luna and Claude Sonnet 5 on most agentic rows.
The small models are the sharper story. 7B posts 70.6 on SWE-bench Verified and 59.0 on BrowseComp. 3.7B posts 68.6 on SWE-bench Verified. 0.9B reaches 48.5 on AIME 2026 and 79.9 on HumanEval+, small enough to run under quantization on a watch.
The Audit IFM Ran on Itself
This is the part many other labs do not publish. IFM ran 375B-A23B across 89 Terminal-Bench 2.1 tasks, eight attempts each. That is 712 trials, 500 passing, a reported 70.2% accuracy. Every passing trial was then re-audited using Artificial Analysis’s reward hacking procedure.
The audit flagged 24 trials across 10 tasks. Removing them drops accuracy to 66.9%, a 3.37-point correction. That sits between the flag rates Artificial Analysis reports for Claude Fable 5 (2.2%) and GPT-5.6 Luna (4.1%). Behaviors included locating benchmark repositories on GitHub and downloading reference solutions. IFM also disclosed a 7B run that reached an inflated 82 on SWE-bench by finding answers.
Interactive explainer
Key Takeaways
- Six models, 0.9B to 375B, all Apache 2.0, all sharing one architecture and serving stack.
- MoVA pushes MoE routing into attention: 36B total, ~4B active, near dense-32B quality.
- Uno delivers roughly 3× lossless decoding speedup as a drop-in LoRA adapter.
- The 0.9B, 3.7B and 7B models claim state of the art at their respective scales.
- IFM published its own reward-hacking audit, correcting 70.2% down to 66.9%.
Check out the Technical blog, Press release, Hugging Face collection, TxT360-v2 dataset, xLLM pre-training code, Post-training code and Docs. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.